You filtered the keyword list to everything under difficulty 30, shipped a new subtitle built from the survivors, and waited. Three weeks later the ranks look the same. The list was not wrong, exactly — it answered a question you did not ask.
An ASO keyword difficulty score is a prediction about competition, made by a tool vendor. It is not a number either store publishes, and neither store has described how such a number would be computed. Knowing what the score is actually made of is what tells you which decisions it can carry and which ones it cannot.
Neither store publishes a difficulty number
Apple states that "Search results are based on a number of factors, including text relevance (matches for your app's title, subtitle, keywords, and primary category), as well as user behavior (downloads, ratings and reviews, and more)" (App Store search, Apple Developer).
Google is blunter about the gap: "Apps are ranked based on a combination of ratings, reviews, downloads, and other factors. While the details of these weights and values are a proprietary part of the Google search algorithm..." (Get discovered on Google Play search, Play Console Help).
That is close to the whole of the public record: two lists of factor names, no weights, no formula, and no per-query score. Every difficulty number you have ever seen was therefore built on top of proxies that a third party could observe from outside the store.
What a difficulty model is made of, and where each input is thin
Difficulty models differ, but they are assembled from a small and fairly predictable set of observable inputs. Each one has a specific weakness worth knowing:
- Who currently ranks for the query. Observable, but only for one storefront, one device class, and one moment. A result set observed in the US on Tuesday is not the result set a French user sees on Friday.
- Strength proxies for those apps — rating count, average rating, chart position, category. Rating counts are cumulative over an app's whole life and are not specific to the query being scored. An app with a very large lifetime review count is not necessarily strong for this search.
- Modeled install or revenue estimates. These are themselves estimates, commonly derived from public signals such as chart position rather than from anything the stores report. Feeding one model's output into another model's input compounds the error rather than cancelling it.
- Text match between the query and visible metadata. Real, and Apple names it explicitly — but Apple's list is expressly open ("a number of factors, including... as well as... and more"), and the other family it names, user behavior, is invisible from outside.
None of this makes difficulty useless. It makes it ordinal, not cardinal: reasonable for saying this query is probably harder than that one, unreliable for saying 32 is achievable and 47 is not.
Three numbers that keep ending up in the same column
The most common reporting failure is a spreadsheet where observed rank, difficulty, and traffic all sit side by side in the same typeface, as if they were the same kind of fact.
| Observed rank | Difficulty score | Volume / traffic score | |
|---|---|---|---|
| Where it comes from | Direct observation of a public storefront | A vendor's model | A vendor's model |
| Needs to be qualified by | Store, country, date, query | Model version, observation date | Model version, observation date |
| Can support | "We were Nth in the US App Store on [date]" | "Order these 40 candidates roughly by contest" | "This term is probably bigger than that one" |
| Cannot support | Anything about another storefront on another day | "We can rank for this" | Any forecast of installs |
If your team cannot tell at a glance which column is an observation and which is a model, the model will eventually get quoted to a stakeholder as a measurement. That is the failure mode worth designing against — the same discipline that keeps rank tracking honest applies here.
A two-week check that tells you whether to trust the score
You do not need to accept a vendor's difficulty on faith, and you do not need a research budget to test it. You need one disciplined pass:
- Pick 15 to 20 keywords you already rank somewhere for, spanning the full difficulty range your tool reports — not just the easy end.
- Record your observed rank for each, with store, country, and date attached. Record "not observed" as its own value; it is not the same as "not ranked."
- Change nothing. No metadata edits, no paid campaigns pointed at those terms, for the whole window.
- Re-observe on the same cadence — say, every third day for two weeks, from the same storefront.
- Compare the orderings. Does the vendor's difficulty ranking of those 20 terms broadly agree with how you actually place across them? You are not looking for a correlation coefficient. You are looking for whether the score's ordering is defensible on your app, in your category, in your market.
A dated keyword observation
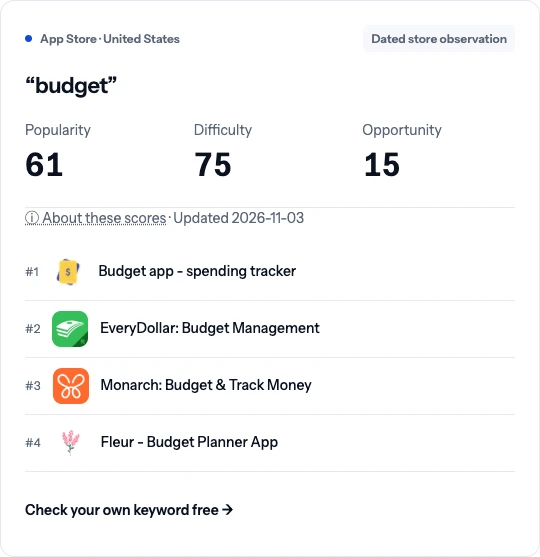
On 2026-11-03, ASOClimb checked budget in the US App Store. Budget app - spending tracker was observed at #1. Popularity was 61, difficulty 75, and opportunity 15. These are comparative scores, not a count of searches or a promise of a future rank.
Check budget yourself. Store positions change; keep the country and observation date alongside each result.
Run that check once per category you work in. A difficulty model tuned on US utility apps may behave quite differently on a Japanese games storefront.
What ASO keyword difficulty should actually decide
Difficulty earns its place at one specific moment: ordering a shortlist of candidates that already passed a relevance test. It is a tiebreaker, not a gate.
The sequence that survives contact with reality is:
- Relevance first. Would someone searching this term be looking for what your app does? A term you can rank for but cannot convert costs you impressions and gives you nothing.
- Intent second. Apple names user behavior among its factors; Google names ratings, reviews and downloads among its own. A term that attracts browsers rather than installers works against you on the kinds of signal both stores say they use.
- Difficulty third, to sequence the work — and to set expectations about how long before you judge a change, not whether to attempt it.
- Field constraints last. Apple's keyword field is a hard budget, so the shortlist has to fit (App Store search).
Inverting that order is how teams end up ranking well for terms nobody who wants their app would type.
What to log so the number stays honest
Every difficulty figure you keep should travel with four things: the tool and model version that produced it, the date it was produced, the storefront and country it describes, and the query exactly as typed. Without those, a six-month-old score is indistinguishable from a current one, and nobody on the team can tell which.
ASOClimb spreads this work across the Keywords Inspector, the Keywords Tracker and the Autocomplete Simulator. Whichever tool you use, keep modelled scores visually distinct from observations in the view your team actually reads — the reporting habit matters more than the tool.
An ASO keyword difficulty score is a reasonable opinion about how crowded a query is. Treat it as an opinion, ask what it was built from, and check it against your own storefront before you let it decide the roadmap. The keyword research workflow it feeds into is what does the real work.